
Mobile work machinery
Digisalix builds the intelligence into vehicles
and machines.
Supervised, not operated
The next generation of work machines will run as autonomous, efficient swarms with people supervising them. Nobody climbing sky high to be grilled in a small glass cube, or digging hundreds of metres down to handle high explosives.
The road there requires many pieces of smarter, environment-aware software.
Those are the parts we build:
Got work machines?
Would you like to make them smarter? Book a chat, let’s figure it out.
Operational autonomy
Path planning and task scheduling
A machine working on its own has to decide what to do next, work out how to do it, and change the plan when reality disagrees — which it will.
We build the algorithms behind that loop:
-
 Path planning Routes around the obstacles that are actually there
-
 Task allocation Work split across machines so they aren’t queueing for the same space
-
 Re-planning A new plan, quickly, when conditions change
The rest of the loop has to hold too: sensing, state estimation, execution on the machine, and communication that survives the site. Those are the problems our team enjoys wrestling with: designing the algorithms, optimisation methods, and models, and taking them from research prototype to production software.
Demos are easy, and we have built a few. Industrial deployments are another matter: the first small setback should not stop the whole operation. That takes robustness, modularity, and fail-safe design. At the prototyping stage, our simulation and task-scheduling work has uncovered design improvements while they were still cheap to make. Our algorithms are built to keep machines moving even when the site doesn’t quite match the map.
We don’t sell an autonomy platform. We solve the hard problems that make one work.
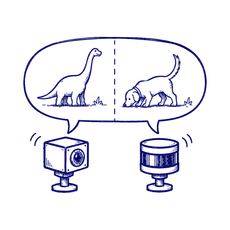
Sensing
Cameras, LiDAR, and the rest, fused into one picture
Sensing forms the basis for autonomous operation, situational awareness, and anticipating future events. Unfortunately, every sensor is confidently wrong about something. Cameras give up in low light, LiDAR reads heavy rain as an obstacle, and no two clocks quite agree. However, fusing those disagreements yields one situational estimate the rest of the system can rely on.
Getting it right means all of this working at once:
-
 Calibration and time alignment Sensors that agree on where they are and when they saw it
-
 Object recognition and tracking What is out there, and where it is heading
-
 State estimation Where the machine actually is and how its task is progressing
-
 Fault detection A bad reading trusted is worse than none
We have worked with live sensor data to establish a machine’s state in its surroundings, flag safety risks early, and predict operation quality. That kind of work draws on statistics, algorithms, and reliable software engineering in equal measure. It also teaches you that a raw reading almost always admits several interpretations. Knowing which of them to take seriously is the judgement we bring to your problem.
A sensing layer that works is a quiet one. It degrades predictably, says when it is unsure, and hands the rest of the system something solid.
Confidence is cheap. Being right takes work.
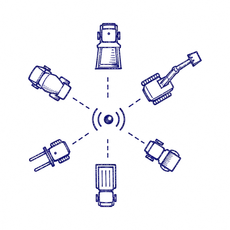
Fleet management
Many machines, one plan
Once the hard work of tracking and remotely controlling machines is done, the operator still has to work out what it all means and decide on actions.
We build the part that comes after:
-
 One operational picture Autonomous machines, human-operated equipment, and people in an area safely
-
 Scheduling and coordination Analytical decisions that maintain the production schedule in changing conditions
-
 Simulation Fleet designs tested, and production gains shown, before anything is bought
-
 The operator’s view Who, what, where, and what’s next, glimpsed in three seconds
None of that is theory for us. We have simulated fleet designs that demonstrated the production gains before the machines were bought, scheduled autonomous machines so they keep working instead of blocking each other, and held the safety case together while the fleet ran.
Algorithms are the core of what we do here. For a fleet, what the operator sees matters just as much. All that scheduling, planning, validating, and simulating has to end up as a view someone can read at a glance. We build the full stack, so the algorithms and the interface get designed together seamlessly.
Those custom interactive tools let you pick a scenario apart in detail, or command and monitor a real fleet. A system, designed this way, tends to surface options nobody had in mind at the start. At its best it handles the routine decisions itself and brings the operator in when a human is genuinely needed.
A fleet needs good management, not babysitting.
Predictive maintenance
Catching failures before things grind to a halt
Modern machinery produces enormous amounts of sensor and telemetry data, from event logs and cameras to microphones, vibration sensors, and other instrumentation. We use that data for condition monitoring, anomaly detection, and predictive maintenance, turning raw signals into better maintenance decisions.
We combine data with knowledge of the system’s physics to identify faults, understand their likely causes, and support human analysis.
Predictive maintenance has a habit of becoming either a threshold alarm or a model trained on three failures and promptly missing the fourth. Failures are rare, which is a sign of excellent engineering, but rather inconvenient for machine learning.
A useful solution starts with the business need
Is the goal to make maintenance visits more efficient, maximise availability, or reduce the risk of an expensive stoppage? Then comes the less glamorous question: what can the available data actually support?
We build what the evidence justifies:
-
 Condition monitoring and anomaly detection Directing human attention to where it is actually needed
-
 Remaining useful life estimates A sound basis for maintenance planning and optimisation,
when the data supports reliable estimates -
 An honest threshold rule With the right variables and proper calibration, sometimes
a threshold is exactly what you need
In the end, much of the difficulty is economic rather than technical. A remaining-life estimate only becomes useful when considered alongside maintenance costs, operational constraints, and the price of unplanned downtime.
That means understanding the business goal, modelling the system properly, and optimising the decisions around it. We are pretty good at that combination.
You don’t need to predict everything. You need to know which machine to open next.
We solve the algorithmic and software part of your R&D dream.
You know the machines and the site. Tell us where the software has to get cleverer — the first conversation costs nothing and usually clarifies a lot.